
In this article, you will learn what DiffusionGemma is, how its diffusion-based text generation differs from standard autoregressive language models, and how to run it with Hugging Face Transformers and vLLM.
Topics we will cover include:
- How DiffusionGemma’s parallel, block-based denoising works, and why it shifts the generation bottleneck from memory bandwidth to compute.
- How to load the model, generate text, watch the denoising process, and use system instructions, thinking mode, and image inputs with Transformers.
- How to serve DiffusionGemma with vLLM, and what Google’s recommended sampling settings actually do.
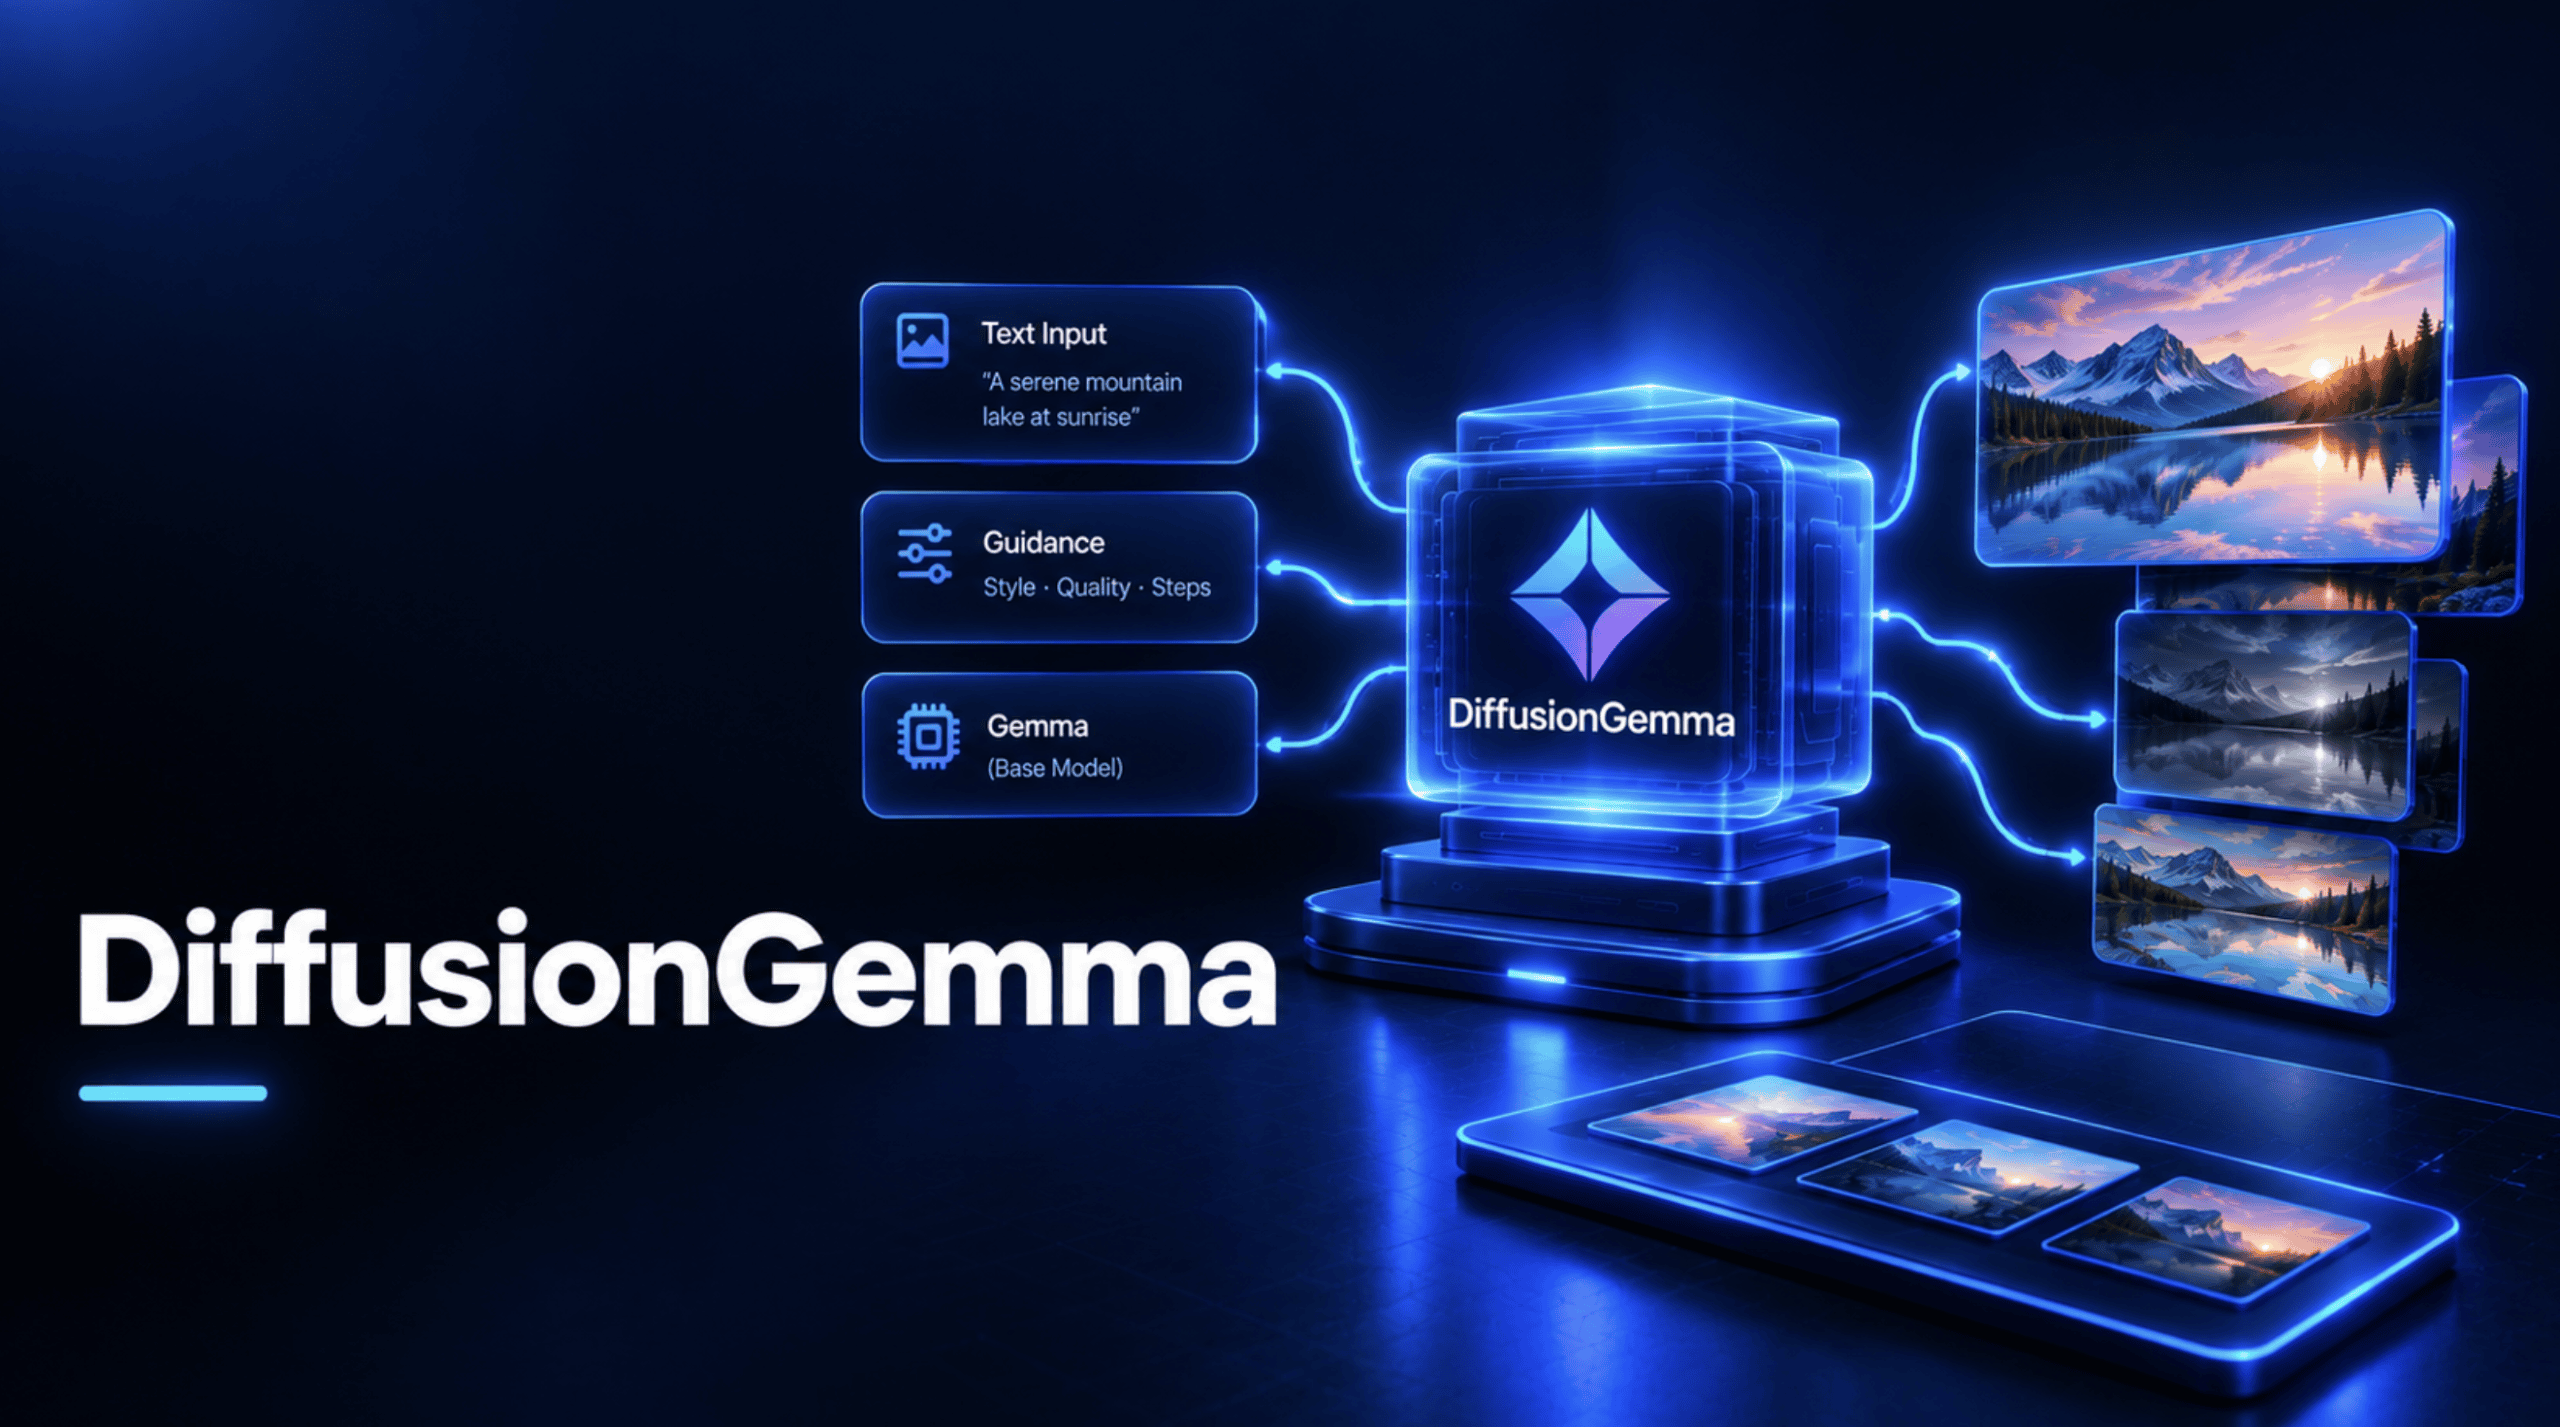
What Is DiffusionGemma?
Every major language model you’ve used — GPT, Claude, Gemini, standard Gemma — generates text the same fundamental way: one token at a time, left to right, each new word conditioned on everything written before it. DiffusionGemma, released by Google DeepMind on June 10, 2026, breaks that pattern entirely. It’s an experimental open model that generates and refines an entire block of text in parallel, using the same diffusion process that made image generators like Stable Diffusion possible, applied to language instead of pixels.
This article covers what DiffusionGemma actually is, how diffusion-based text generation differs mechanically from the autoregressive approach every other major LLM uses, and a real, hands-on walkthrough of using it: loading the model, generating your first response, watching the diffusion process happen in real time, and serving it in production.
DiffusionGemma is built on the same architecture as the Gemma 4 26B model, a Mixture-of-Experts design with 26 billion total parameters but only 3.8 billion active per token. The “A4B” naming you’ll see attached to it refers to that active-parameter count. It’s released under the Apache 2.0 license as an experimental model, meaning Google is explicit that this is a research and development preview rather than a finished, stable product.
A few specifics are worth knowing upfront. It’s multimodal on the input side, accepting text, images (with variable aspect ratio and resolution), and video, though notably not audio, while always producing text as output. Quantized, it fits within an 18GB VRAM budget, putting it within reach of a single high-end consumer GPU like an RTX 4090 or 5090 for local use. And it ships with a built-in, configurable thinking mode, letting the model work through a problem step by step in a separate reasoning channel before committing to a final answer — a feature you’ll see demonstrated later in this article.
How Diffusion Text Generation Differs from Traditional Generation
A standard autoregressive model like GPT-4 or a normal Gemma model generates one token, appends it to the sequence, feeds the whole thing back in, and generates the next token, repeating until it’s done. The real bottleneck in that process, especially for a single user running locally, isn’t compute; it’s memory bandwidth: the model has to repeatedly load its full weights from memory just to produce one token at a time, leaving the GPU’s actual compute cores mostly idle while it waits for that data to move. And because generation is strictly sequential, an autoregressive model can never revise something it already wrote. Once a token is committed, it’s permanent, which is exactly why these models sometimes paint themselves into a corner partway through a complex answer with no way to backtrack.
DiffusionGemma inverts both of those constraints. Instead of generating one token at a time, it starts with a canvas of 256 placeholder tokens — essentially random noise — and denoises the entire block simultaneously across multiple passes. Under what Google calls Uniform State Diffusion, the tokens the model is most confident about help resolve the ones it’s less sure of, and the whole sequence gradually snaps into focus rather than being written in order. This shifts the actual bottleneck from memory bandwidth to compute, since the GPU now has a large, genuinely parallel workload to chew on instead of sitting idle between sequential steps, which is what makes the speed gains possible in the first place.
For sequences longer than one 256-token canvas, DiffusionGemma uses what Google calls block-autoregressive denoising. Once a canvas is fully resolved, it gets committed to the model’s KV cache using ordinary causal attention, the same mechanism a standard autoregressive model uses, and a fresh 256-token canvas starts denoising, conditioned on everything committed so far. That combination is deliberate: causal, sequential attention for the committed history keeps long-form generation stable, while bidirectional attention within each active canvas, where any token can attend to any other token in the same block, enables both the parallel speed and a genuinely new capability: self-correction. If a token’s confidence drops partway through denoising, the sampler can re-noise it and let the model try again, something an autoregressive model structurally cannot do once a token is already written.
Setup
Hardware: Google’s own cookbook notebook specifies a GPU with more than 60GB of memory, such as an A100 or H100-class card, for the full, unquantized model. For local use on consumer hardware, the quantized build targeting an 18GB VRAM footprint is the realistic path on a card like an RTX 4090 or 5090.
Software:
|
1 2 3 4 5 |
# Install PyTorch and other core libraries pip install torch accelerate # Install the transformers library (this specific version or newer is required) pip install "transformers>=5.11.0" |
The version pin on transformers isn’t a suggestion: DiffusionGemma’s block-diffusion architecture requires model classes that only exist in transformers 5.11.0 and later, and an older version will fail to recognize the model entirely.
The model weights are released under the Apache 2.0 license, permissive enough for most commercial and research use, though it’s worth reading Gemma’s own prohibited use policy before deploying it in anything customer-facing.
Loading the Model
|
1 2 3 4 5 6 7 8 |
from transformers import DiffusionGemmaForBlockDiffusion, AutoProcessor MODEL_ID = "google/diffusiongemma-26B-A4B-it" model = DiffusionGemmaForBlockDiffusion.from_pretrained( MODEL_ID, dtype="auto", device_map="auto", ) processor = AutoProcessor.from_pretrained(MODEL_ID) |
DiffusionGemmaForBlockDiffusion is a dedicated model class, not the standard AutoModelForCausalLM you’d use for a normal Gemma model, since block diffusion needs its own generation logic for the denoising loop rather than the simple next-token sampling an autoregressive class implements. dtype=”auto” lets transformers pick the most efficient precision your hardware supports, and device_map=”auto” handles distributing the model across available GPU memory automatically. AutoProcessor, rather than a plain tokenizer, is used here because DiffusionGemma needs to handle image and video inputs alongside text, not just text tokenization.
Your First Generation
|
1 2 3 4 5 6 7 8 9 10 11 12 |
message = [ {"role": "user", "content": "Why is the sky blue?"} ] input_ids = processor.apply_chat_template( message, tokenize=True, add_generation_prompt=True, return_dict=True, return_tensors="pt", ).to(model.device) output = model.generate(**input_ids, max_new_tokens=512) text = processor.decode(output[0], skip_special_tokens=False) print(text) |
apply_chat_template wraps your message in DiffusionGemma’s specific turn-based format (internally using tokens like user and model to mark who’s speaking), the same kind of structured prompting standard Gemma models use, and add_generation_prompt=True tells it to leave the prompt ready for the model to start responding. model.generate runs the actual denoising loop under the hood, iterating over each 256-token canvas until it converges, and max_new_tokens=512 caps how much it’s allowed to generate across as many canvas blocks as needed.
Watching the Diffusion Process with TextDiffusionStreamer
This is the single most useful tool for actually understanding what’s happening mechanically, rather than just taking the “parallel denoising” explanation on faith.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 |
from transformers import TextDiffusionStreamer streamer = TextDiffusionStreamer(tokenizer=processor.tokenizer) message = [ {"role": "user", "content": "Why is the sky blue?"} ] input_ids = processor.apply_chat_template( message, tokenize=True, add_generation_prompt=True, return_dict=True, return_tensors="pt", ).to(model.device) output = model.generate(**input_ids, max_new_tokens=512, streamer=streamer) text = processor.decode(output[0], skip_special_tokens=False) print("\n-- Final Output --") print(text) |
TextDiffusionStreamer intercepts and prints the canvas’s state after each denoising step rather than waiting for the final result, giving you a direct window into the refinement process.
System Instructions and Thinking Mode
|
1 2 3 4 5 6 7 8 9 10 11 12 |
message = [ {"role": "system", "content": "Speak like a pirate."}, {"role": "user", "content": "Why is the sky blue?"}, ] input_ids = processor.apply_chat_template( message, tokenize=True, add_generation_prompt=True, return_dict=True, return_tensors="pt", ).to(model.device) output = model.generate(**input_ids, max_new_tokens=512) print(processor.decode(output[0], skip_special_tokens=False)) |
A system role message works exactly as it would with any standard Gemma model, steering tone and behavior before the actual user turn. DiffusionGemma’s chat template inserts it as its own distinct turn ahead of the user’s message, and the model reliably carries that instruction’s style through the entire generated response.
For step-by-step reasoning before a final answer, enable thinking mode explicitly:
|
1 2 3 4 5 6 7 8 9 |
message = [{"role": "user", "content": "What is the water formula?"}] input_ids = processor.apply_chat_template( message, tokenize=True, add_generation_prompt=True, return_dict=True, return_tensors="pt", enable_thinking=True, ).to(model.device) output = model.generate(**input_ids, max_new_tokens=512) print(processor.decode(output[0], skip_special_tokens=False)) |
enable_thinking=True is the one extra argument that changes everything here; it tells the processor to insert the correct special tokens marking a separate reasoning channel, where the model works out its answer in a thought block before producing the final, user-facing response. Because the code decodes with skip_special_tokens=False, that thought block is visible in the printed output.
Multimodal Input: Image Understanding
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 |
from PIL import Image import requests img_url = "https://raw.githubusercontent.com/google-gemma/cookbook/refs/heads/main/apps/sample-data/GoldenGate.png" input_image = Image.open(requests.get(img_url, stream=True).raw) message = [ { "role": "user", "content": [ {"type": "image", "url": img_url}, {"type": "text", "text": "What is shown in this image?"}, ], } ] input_ids = processor.apply_chat_template( message, tokenize=True, add_generation_prompt=True, return_dict=True, return_tensors="pt", ).to(model.device) output = model.generate(**input_ids, max_new_tokens=512) print(processor.decode(output[0], skip_special_tokens=False)) |
The content field becomes a list rather than a plain string the moment you’re mixing modalities: an image entry followed by a text entry. The processor handles converting the actual image into the sequence of internal image tokens the model expects, entirely automatically. Remember that DiffusionGemma accepts images and video as input but only ever produces text as output. This isn’t an image generation model wearing a diffusion label; the diffusion process here is applied purely to the text output side.
Serving DiffusionGemma in Production with vLLM
For anything beyond local experimentation, Google worked directly with the vLLM team to integrate DiffusionGemma’s iterative denoising loop into vLLM’s standard serving engine:
|
1 2 3 4 5 6 7 8 9 |
vllm serve google/diffusiongemma-26B-A4B-it \ --max-model-len 262144 \ --max-num-seqs 4 \ --gpu-memory-utilization 0.85 \ --attention-backend TRITON_ATTN \ --generation-config vllm \ --hf-overrides '{"diffusion_sampler": "entropy_bound", "diffusion_entropy_bound": 0.1}' \ --diffusion-config '{"canvas_length": 256}' \ --enable-chunked-prefill |
Most of these flags are standard vLLM serving options: –max-model-len sets the context window, –max-num-seqs caps concurrent sequences (kept deliberately low here, since the model is designed for low-concurrency use), and –gpu-memory-utilization sets how much VRAM vLLM is allowed to claim. The two flags specific to this model are the interesting part: –hf-overrides with “diffusion_sampler”: “entropy_bound” and “diffusion_entropy_bound”: 0.1 configures the token-selection strategy during denoising, described in more detail in the next section, and –diffusion-config ‘{“canvas_length”: 256}’ sets the block size the model denoises at once, matching its trained 256-token canvas. Once running, this exposes a standard OpenAI-compatible local server, meaning any tool built against that API format works with DiffusionGemma with no code changes beyond pointing it at the new endpoint.
Recommended Sampling Configuration
Google publishes specific recommended defaults for the diffusion sampling process itself, which are worth understanding rather than treating as opaque numbers:
| Parameter | Recommended Value | What It Does |
|---|---|---|
| Maximum denoising steps | 48 | Upper bound per canvas; adaptive stopping typically halts earlier, around 12-16 steps |
| Temperature schedule | Linear 0.8 → 0.4 | Starts high to encourage exploration, drops to lock in final tokens |
| Adaptive early stopping | Entropy threshold: 0.005 | Halts a canvas early once average confidence is high and two consecutive passes agree |
| Token selection | Entropy bound: 0.1 | Commits only the lowest-entropy (most confident) tokens each step, re-noising the rest |
In practice, the temperature schedule is the clearest illustration of how differently this model behaves from a standard LLM with a single, fixed temperature setting: it deliberately starts uncertain and gets more decisive as denoising progresses, mirroring how the canvas itself moves from noise to resolved text. The entropy-bound token selection is what actually produces the model’s self-correction behavior: rather than accepting every token’s guess on every pass, it only locks in the ones it’s confident about and leaves everything else open to revision in the next step.
Wrapping Up
The honest bar for reaching for DiffusionGemma over a standard autoregressive Gemma model comes down to your actual constraint. If you’re serving thousands of concurrent requests in the cloud, autoregressive generation’s mature batching story still wins; Google says as much about this model itself.
But if you’re running inference locally on your own hardware, for a single user, at low concurrency, where a normal model leaves your GPU’s compute mostly idle waiting on memory bandwidth, DiffusionGemma’s entire design exists to fix exactly that problem.


No comments yet.