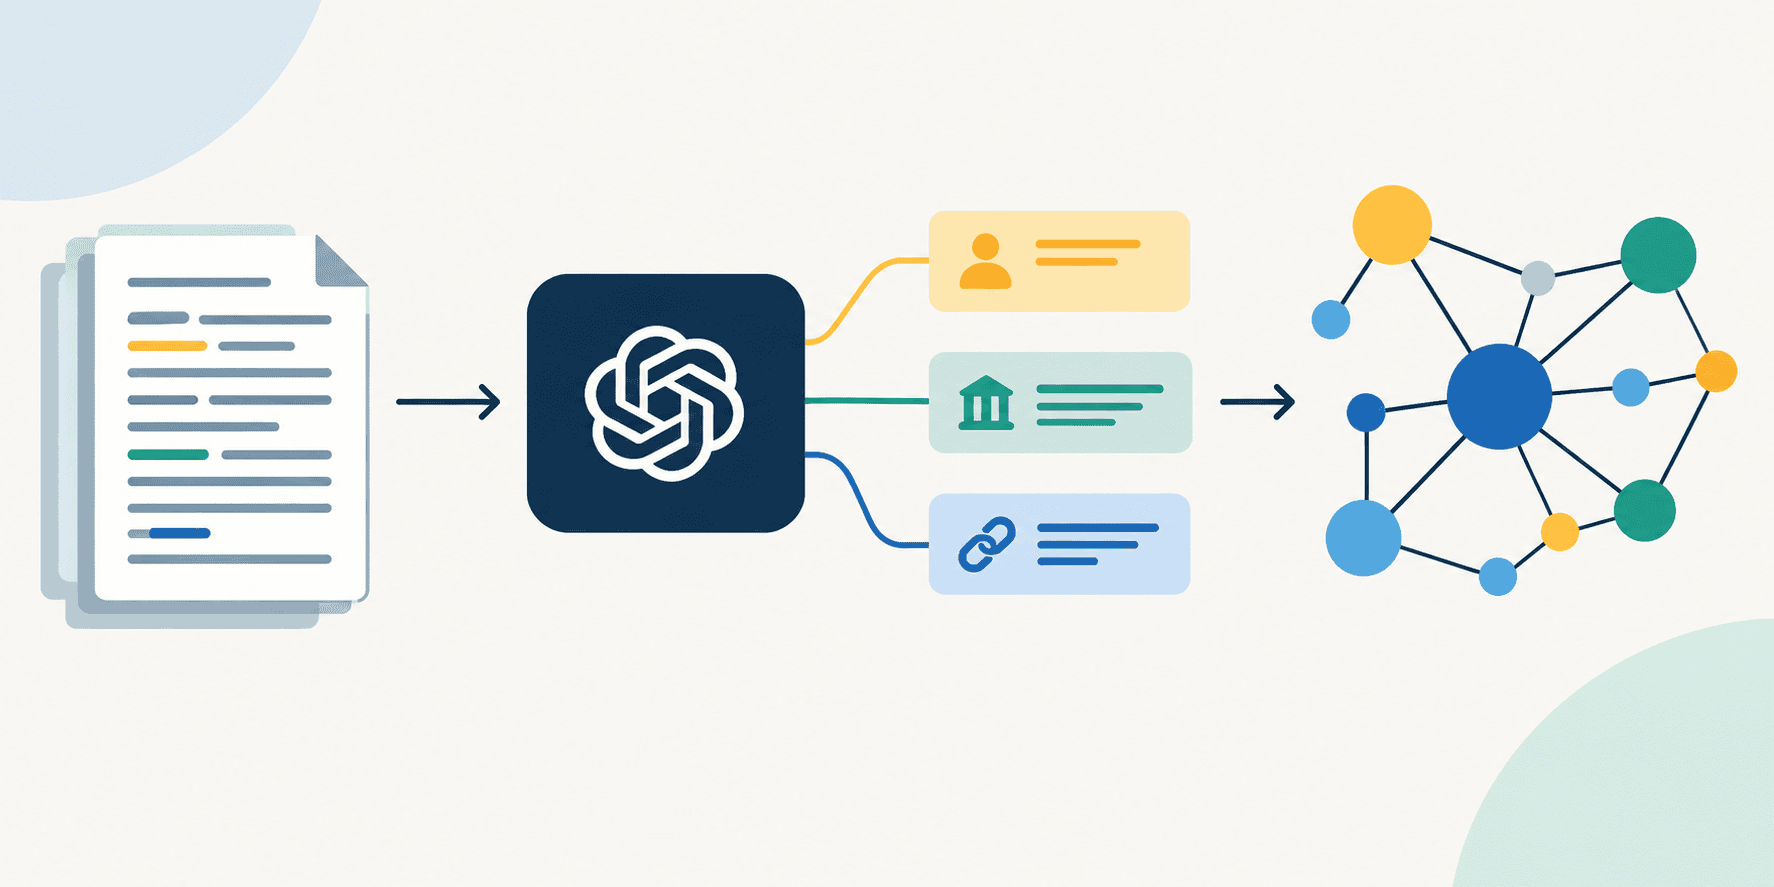
In this article, you will learn how to automatically extract structured knowledge from raw text and populate a knowledge graph with SPOC quads using a local LLM via Ollama.
Topics we will cover include:
How to set up Ollama with the Llama 3.2 model to run a free, local LLM for structured data extraction.
How to design a robust extraction pipeline that converts unstructured Wikipedia text into SPOC (Subject-Predicate-Object-Context) quads using few-shot prompting and JSON output mode.
How to load the extracted quads into a QuadStore knowledge graph, ready for use in a Graph-RAG retrieval pipeline.
Introduction
The recent article on Building a Deterministic 3-Tiered Graph-RAG System shows how a hierarchical, graph-based architecture can tackle the issue of hallucinations in standard vector information retrieval.
That article leveraged Quadstore, a lightweight knowledge graph database implemented in Python, to teach LLMs to respect ground-truth facts, thereby ensuring factual accuracy and deterministic retrieval conflict resolution in applications like RAG systems.
A critical question remains, though: where does the factual graph knowledge come from? This article helps close the loop, showing a free, fully automated approach to extract entities and build SPOC quads (Subject-Predicate-Object-Context) from raw text such as Wikipedia pages. We will do this with the help of a local, free LLM from Ollama. Once these quads are built, we will illustrate how to directly populate the Quadstore.
Prerequisites and Setup
The workflow shown in this article is designed to run seamlessly both in a Google Colab notebook and in your local Python IDE. If you choose the latter, you will need to manually install Ollama on your computer first, along with pulling the Llama 3.2 model locally.
In Google Colab, you can set up Ollama and get Llama 3.2 for your open session using these commands:
1
2
!apt-get update-qq&&apt-get install-y-qq zstd
!curl-fsSL https://ollama.com/install.sh | sh
Either way, you will need to install these two libraries as well:
1
!pip install wikipedia requests
Llama 3.2 is a lightweight, free model. Its API is configured to strictly operate in JSON input/output mode, a mandatory standard for reliable data extraction. Using subprocess, we can start the Ollama server as a background process and pull our target model:
# 2. Pulling the Llama 3.2 model (this may take a minute or two on Colab)
print("Pulling Llama 3.2...")
subprocess.run(["ollama","pull","llama3.2"])
print("Model ready!")
Automated Knowledge Graph Population
Let’s look at the process of constructing our knowledge graph from a source of raw text. We will convert narrative text into strictly modeled relationships that extend classical RDF triples of the form (Subject, Predicate, Object) by adding a fourth dimension: the context. This is useful for tracking where a fact comes from and whether it is true or not.
A triple like ("LeBron James", "plays_for", "Lakers") thus becomes ("LeBron James", "plays_for", "Lakers", "NBA_2023_Roster").
First, we will create a small, simulated QuadStore engine that mimics the framework used in the related article this one follows up on. If you are working in a notebook, run this code in a separate cell to generate a quadstore.py file in your workspace on the fly:
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
%%writefilequadstore.py
classQuadStore:
def __init__(self):
# Using a simple list to store the facts for our lightweight implementation
self.quads=[]
def add(self,subject,predicate,obj,context):
"""Adds a new SPOC quad to the knowledge graph."""
"""Queries the graph. Returns a list of quads that match the provided criteria."""
results=[]
forq_sub,q_pred,q_obj,q_ctx inself.quads:
if(subject isNone orsubject==q_sub)and\
(predicate isNone orpredicate==q_pred)and\
(obj isNone orobj==q_obj)and\
(context isNone orcontext==q_ctx):
results.append((q_sub,q_pred,q_obj,q_ctx))
returnresults
A file containing exactly the above code will be created, and we will refer to it later on just like any other Python module, to demonstrate how to load our created knowledge graph into our mock Graph-RAG system.
Back to the main process: we will now pull some raw text from Wikipedia using the namesake API. The auto_suggest=False option ensures we correctly fetch the right article name from Wikipedia without automated corrections that may cause a crash.
1
2
3
4
5
6
7
8
9
10
11
12
import wikipedia
print("Fetching Wikipedia summary...")
# Disabling auto_suggest to prevent the library from renaming "Turing" to "tuning"
# We'll just take the first two paragraphs of the Wikipedia page to keep extraction fast
paragraphs=text_content.split('\n')[:2]
short_text=" ".join(paragraphs)
print(f"Extracted {len(short_text)} characters of text ready for processing.")
Output:
1
2
Fetching Wikipedia summary...
Extracted1244characters of text ready forprocessing.
Now comes the core of the entire workflow: the robust extraction engine, modeled by the following function that:
Works with the target LLM’s formatting engine to extract structured data in the form of quads. To do this, we use few-shot examples as part of the prompt sent to the LLM.
Post-processes the LLM output to extract a list of facts and build a list of quads accordingly.
S:Alan Mathison Turing|P:devised techniques for|O:speeding the breaking of German ciphers|C:Wikipedia_Alan_Turing
S:Alan Mathison Turing|P:playedacrucial role in|O:cracking intercepted messages that enabled the Allies todefeat the Axis powers|C:Wikipedia_Alan_Turing
S:Alan Mathison Turing|P:is|O:widely considered tobe the father of theoretical computer science|C:Wikipedia_Alan_Turing
S:Alan Mathison Turing|P:was|O:influential inthe development of theoretical computer science|C:Wikipedia_Alan_Turing
From just two paragraphs of Alan Turing’s Wikipedia article, we extracted around 11 facts, structured as quads. Note that the exact number may vary slightly due to the non-deterministic behavior of the LLM.
We wrap up by seeing how to add these facts into the QuadStore object:
1
2
3
4
5
6
7
8
9
10
11
12
13
from quadstore import QuadStore
facts_qs=QuadStore()
forquad inextracted_quads:
facts_qs.add(
quad["subject"],
quad["predicate"],
quad["object"],
quad["context"]
)
print(f"Successfully loaded {len(extracted_quads)} automated facts into the Graph RAG system!")
Output:
1
Successfully loaded11automated facts into the Graph RAG system!
Conclusion
This article closed the loop on our deterministic 3-tiered Graph-RAG architecture by showing how to build a knowledge graph consisting of facts extracted directly from unstructured text in the form of quads — all from scratch. You can now integrate this knowledge into your retrieval pipeline to help eliminate issues like LLM hallucinations.




Hi need jobs my skills airtfice intelligence and cloud computing lot of sikles