In this article, you will learn what model distillation is, how it has evolved for large language models, and why it has become one of the most contested topics in the AI industry.
Topics we will cover include:
How classical distillation works, including the concept of “dark knowledge” and temperature scaling.
How modern distillation techniques have adapted for large language models, covering synthetic data, feature, and logit-based approaches.
Why unauthorized distillation at scale has triggered major industry controversy and what the structural tensions driving it mean for the future.
Let’s not waste any more time.
Introduction
The most capable AI models in the world are also among the most impractical. Models like GPT-4, Claude, and Gemini contain hundreds of billions of parameters and require entire data centers to run. They are expensive, slow, and impossible to deploy on a smartphone, a browser, or any environment where computing resources are limited.
This creates a genuine problem: how do you take a model that cost hundreds of millions of dollars to train and make it available to the world at a reasonable cost and speed?
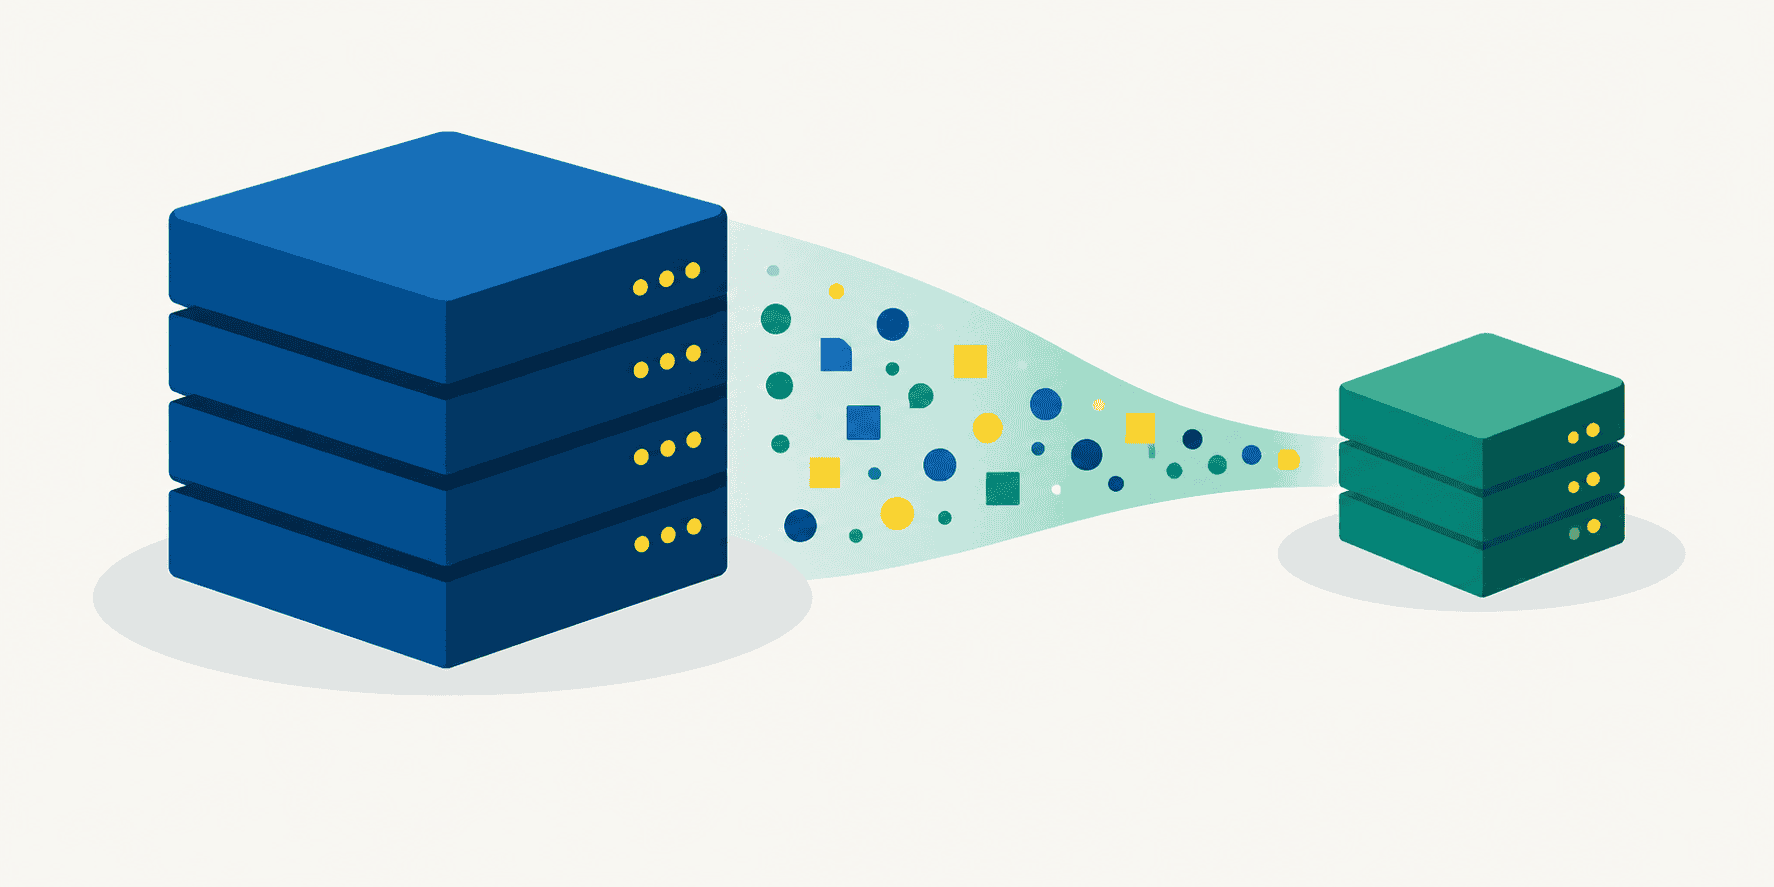
One of the most effective answers is model distillation, a technique where a smaller “student” model learns to replicate the behavior of a much larger “teacher” model. The student ends up a fraction of the size but retains a surprising amount of the teacher’s capability. This article explains how that works, how the approach has evolved for modern large language models, and why it has become one of the most contested topics in the AI industry.
What a Model Actually Learns
To understand distillation, it helps to start with how a standard model learns.
In a conventional image classification task, a model trains on labeled photos. Each photo comes with a hard label: this is a dog, that is a cat. The model adjusts its parameters until it reliably predicts the correct label. The training signal is binary: right or wrong.
The problem is that hard labels discard a lot of information. A photo of a golden retriever does not just contain “dog” information. It also contains information that dogs look somewhat like cats, that both look nothing like cars, and that certain dog breeds are more visually ambiguous than others. None of that relational structure appears in a simple label.
A trained teacher model, however, has already absorbed this structure. When it looks at that photo of a golden retriever, it does not just output “dog.” It outputs a probability distribution: perhaps 85% dog, 13% cat, 2% wolf, near-zero for everything else. These distributions reflect the model’s learned sense of similarity between concepts. Geoffrey Hinton, who developed the foundational distillation framework, called the information embedded in these distributions “dark knowledge” — knowledge that exists in the model but is invisible in the raw labels.
How Classical Distillation Works
The central insight of distillation is simple: instead of training the student on hard labels, train it on the teacher’s probability distributions. The student learns not just what the right answer is, but the teacher’s full sense of which wrong answers are more plausible than others. This is a richer signal, and it transfers generalization capability in a way that hard labels cannot.
There is one practical complication. At normal confidence, a teacher model tends to produce very peaked distributions, assigning 99% probability to the correct class and near-zero to everything else. That distribution is barely more informative than a hard label. To expose the subtle relationships between classes, distillation uses a technique called temperature scaling. Increasing the temperature “softens” the distribution, flattening it out so the smaller differences between classes become visible. The student trains on these softened distributions.
The student also trains against the original ground-truth labels at the same time. The final training objective is a blend of two goals: match the teacher’s soft outputs, and get the actual answers right. A single weighting parameter controls the balance between the two. In practice, heavier weight on the teacher’s soft distributions tends to produce better results.
Hinton, Vinyals, and Dean published this framework in 2015 and demonstrated it on speech recognition and image classification. Small distilled models were able to match the performance of much larger model ensembles, suggesting that the teacher’s dark knowledge was being successfully transferred.
Modern Distillation: How Large Language Models Do It
Classical distillation works well for tasks with a fixed set of output classes. Large language models present a different challenge. They generate text token by token across vocabularies that can exceed 100,000 tokens. The probability distribution at each step is enormous, and the structure of the problem is fundamentally sequential rather than categorical. The classical framework does not transfer cleanly.
Modern distillation has adapted into three main approaches.
Synthetic data distillation is now the dominant method. Rather than matching probability distributions, the teacher generates large volumes of high-quality text, which the student then learns from directly. Step-by-step reasoning chains, worked examples, code solutions, structured analysis: the teacher produces these at scale, and the student is fine-tuned on this synthetic dataset. This approach requires only access to the teacher’s text outputs, not its internal architecture or weights.
Feature distillation takes a different path. Rather than matching the teacher’s final outputs, the student learns to replicate the teacher’s internal representations — the patterns of activation at intermediate layers. This transfers a deeper structural understanding of how the teacher processes information, but it requires full access to the teacher’s architecture. It is typically used when an organization is distilling its own models.
Logit-based distillation applies a version of the classical framework at the token level, matching the teacher’s full token probability distributions rather than just the sampled text. This also requires white-box access to the teacher’s internals and is used primarily in-house.
The distinction between these approaches has significant practical consequences. Synthetic data distillation requires only API access to the teacher’s text outputs, which means it can be applied to any model that offers a public interface. Feature and logit-based distillation require access to the model’s internals, which limits them to cases where the distilling organization controls the teacher. This distinction sits at the center of the industry’s current controversy over unauthorized distillation.
Distillation as Standard Practice
Before engaging with the controversy, it is worth establishing that distillation is entirely normal engineering practice.
Meta designed its Llama 3.1 405B model explicitly to serve as a teacher for distillation. Its license permits using the 405B’s outputs to train smaller variants like the 8B and 70B models. Synthetic data generation and distillation are listed as primary intended use cases.
Every major AI lab routinely distills its own large models into smaller, cheaper versions for different product tiers and deployment contexts. Much of the open-source AI ecosystem is built on this foundation: models like Alpaca and Vicuna were fine-tuned on synthetic data generated by larger models.
Distillation itself is not controversial. The controversy is about whose model you distill, and whether you have permission to do so.
The Controversy: Unauthorized Distillation at Scale
In early 2026, several major AI labs made public allegations of systematic unauthorized distillation targeting their models.
OpenAI submitted a memo to the US House Select Committee on China alleging that DeepSeek had used obfuscated methods, including third-party routing, to extract capabilities from its models. Anthropic published a detailed account of approximately 24,000 fake accounts generating over 16 million exchanges with Claude, with the activity specifically targeting Claude’s most differentiated capabilities: agentic reasoning, tool use, and coding. Google disclosed that its Threat Intelligence Group had identified and disrupted distillation attacks targeting Gemini involving more than 100,000 prompts.
In June 2026, Anthropic alleged that Alibaba’s Qwen lab had run the largest known campaign: roughly 25,000 fake accounts generating 28.8 million exchanges with Claude over a 44-day window. Alibaba denied the allegations.
What made these allegations notable was not the technique itself. It was the scale, the systematic circumvention of access controls, and the apparent targeting of specific capabilities. This is qualitatively different from a researcher experimenting with a public API.
It is also worth noting that this is not exclusively a story about Chinese labs. During testimony in his lawsuit against OpenAI in April 2026, Elon Musk acknowledged under oath that xAI had “partly” used OpenAI’s models in training Grok, characterizing this as standard practice across the industry.
There is also the question of DeepSeek’s costs. Its technical report claimed that training DeepSeek V3 cost approximately $5.6 million in compute. Independent analysis from SemiAnalysis estimated total investment at around $1.3 billion, accounting for prior research and infrastructure. If unauthorized distillation contributed to efficiency gains, the published figures may understate the true cost by externalizing a portion of the R&D expense onto the labs whose models were allegedly harvested. This remains unproven.
One clarification is worth making directly: no independent forensic audit has been published for any of these allegations. No court has ruled on any distillation-related claim. The accused labs have either denied wrongdoing or declined to respond publicly. The legal framework remains unsettled, partly because AI outputs generally cannot be copyrighted under US law, which means enforcement typically relies on terms-of-service violations — a mechanism that faces real challenges when the accused party is a foreign entity.
A Structural Problem Without a Clean Solution
The deeper issue that distillation exposes is not about any particular lab or country. It is structural.
If a model is capable enough to generate valuable outputs for customers through an API, those same outputs contain enough signal to train a smaller model to replicate much of that capability. Making a model commercially available and protecting the investment that built it are, at some level, in tension with each other.
The industry is now exploring technical defenses including anomaly detection, output watermarking, and rate limiting. Legal strategies include more aggressive terms-of-service enforcement and legislative advocacy. OpenAI, Anthropic, and Google have reportedly begun sharing anti-distillation intelligence.
None of these solutions is straightforward. Watermarking can be stripped. Rate limiting affects legitimate users. Jurisdictional gaps complicate legal enforcement. The challenge of making powerful AI systems available without making them trivially replicable may not have a clean resolution, which means distillation will remain both a legitimate engineering technique and a contested frontier for the foreseeable future.
Key Takeaways
Distillation transfers a large model’s learned knowledge to a smaller model, enabling capable but efficient systems that would be impractical to deploy otherwise. Classical distillation works by training a student on the teacher’s soft probability distributions rather than hard labels, transferring what Hinton called dark knowledge. Modern distillation for large language models relies primarily on synthetic data generation, where the teacher produces high-quality text that the student learns from directly.
Distillation is standard, legitimate engineering practice across the entire industry. The controversy centers on unauthorized distillation at scale, where the technique is applied without permission across organizational boundaries. The legal and technical frameworks for addressing this are still developing, and the structural tension between deployment and protection shows no signs of resolving quickly.


No comments yet.